8
3
Kent C. Dodds Hasn't Looked at His Code All Year
17 Min Read
At the start of this year, Kent C. Dodds gave a coding agent a link to a GitHub issue he had been...
8
3
17 Min Read
At the start of this year, Kent C. Dodds gave a coding agent a link to a GitHub issue he had been...
143
32
4 Min Read
A few weeks ago we teamed up with Kaggle to ask a deceptively simple question: how do you actually...
55
6
4 Min Read
In my last post, I wrote about moving Forem’s performance and maintenance work into autonomous loops...
19
3
13 Min Read
llama.cpp, vLLM, SGLang, mistral.rs, a plain PyTorch engine and LiteRT-LM serve the same 4-bit Gemma 4 E2B on one 16 GB Tesla T4 on Compute Engine, with the same prompts, load sweep and GSM8K and BFCL questions. GSM8K and BFCL are level on every CUDA engine; vLLM with its drafter leads at every load.
11
4
6 Min Read
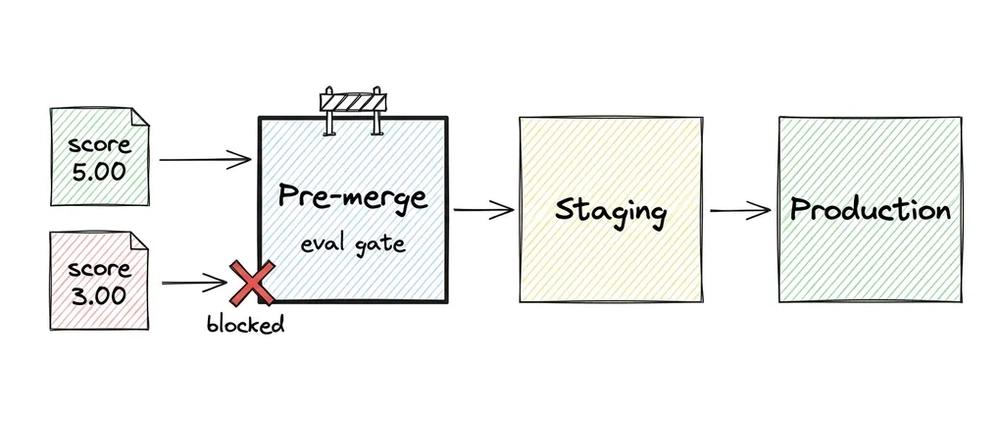
How to make a quality drop fail your build with agents-cli eval run and one threshold, for anyone who ships an agent from a pipeline.
20
13 Min Read
Verifiable classroom attendance and keylogger-proof proctored exam lab sign-in with FIDO2 WebAuthn Passkeys, 15s rotating HMAC QRs, and GCIP blocking hooks.
15
1
1 Min Read
Want AI to answer in a specific way? Don't just tell it. Show it. In this episode of Prompt Pad,...
140
56
3 Min Read
Last week you showed me where you code. This week I want to know how you ended up there in the first...
9
8 Min Read
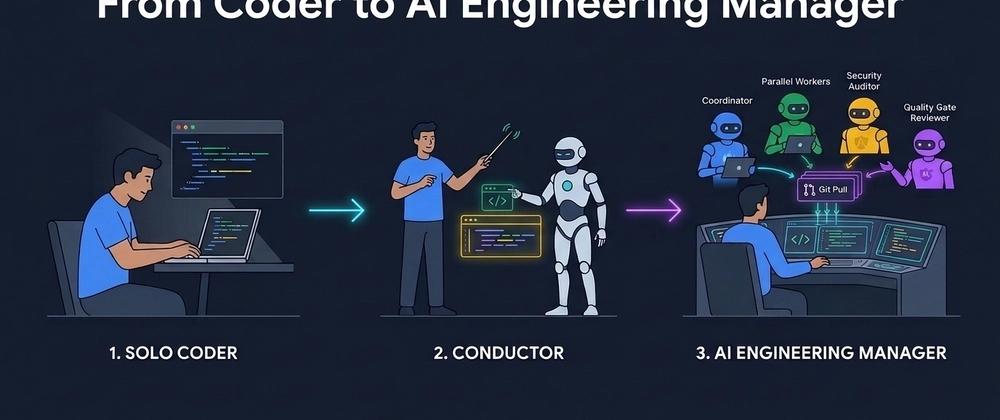
How my workflow evolved from solo prompting in AI Studio to managing a multi-model AI team, running...
72
9
5 Min Read
When DHH took the stage at Rails World 2026 and talked openly about going "pencils down" on...
9
1
16 Min Read
The same currency agent built on A2UI 0.9 and on A2UI 1.0: what changed in the protocol, how an answer reaches the screen now, and why the model writes 21 tokens for a rate card that took 223 on 0.9.
29
18
2 Min Read
If you’ve been in the software industry for any length of time, you’ve probably heard people talking...
12
1 Min Read
When people call an AI model "open," they don't always mean the same thing. On this week's Prompt...
17
1
16 Min Read
Interactive Classroom Bingo comprehension checks and zero-trust proctored exam lockdown with forensic .docx dossiers on Google Cloud.
11
3
5 Min Read
Overview I've been using Vue.js since the early days, long enough that "Evangelion" sounds...
10
4
6 Min Read
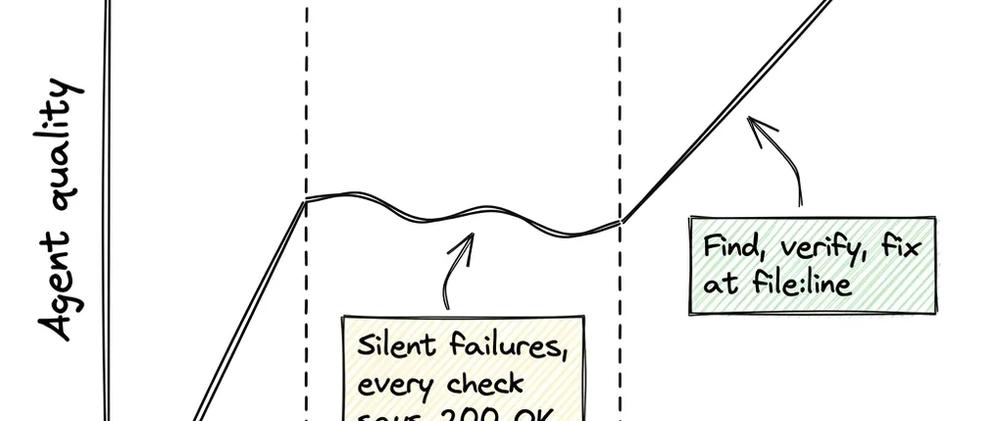
AQuA is an open-source quality agent that surfaces the production failures your health checks miss and, when you ask, traces a failure to the line of code behind it. Try its dashboard locally.
121
87
1 Min Read
👋👋👋👋 Looking back on your week -- what was something you're proud of? All wins count -- big or small...